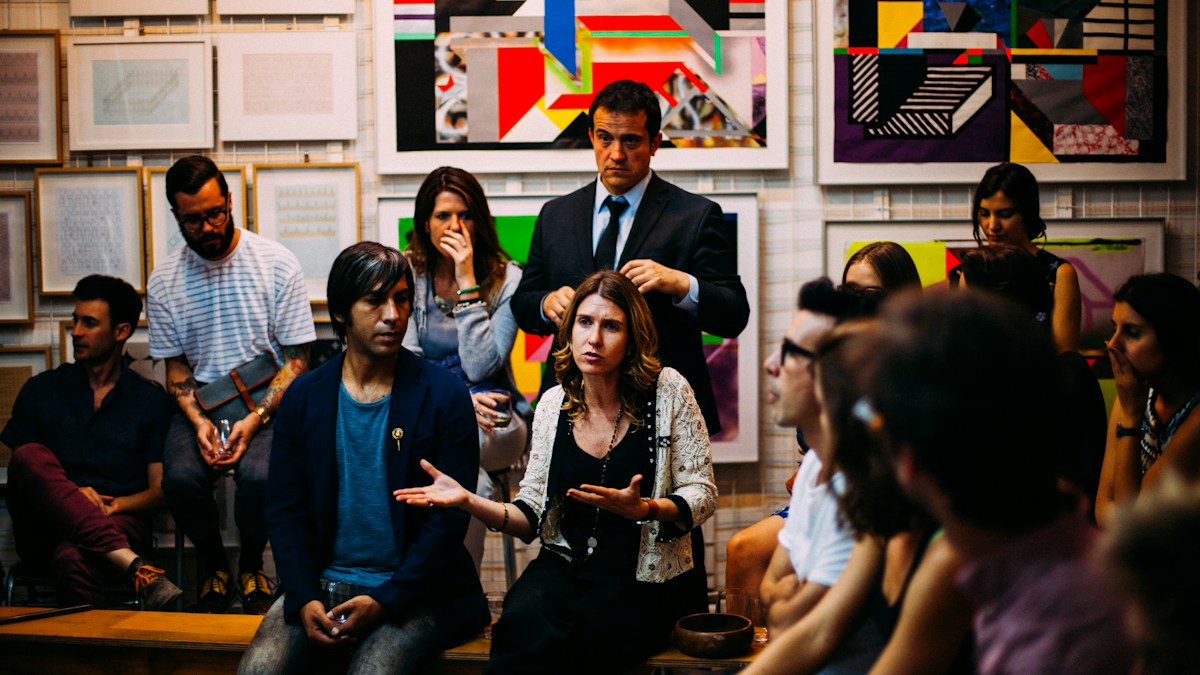
A high-level gathering of technological innovators, philanthropic leaders, and government regulators in Washington has yielded a detailed consensus framework for evaluating the systemic risks of advanced machine learning models.
The summit focused on establishing empirical benchmarks capable of measuring when an artificial intelligence system demonstrates dangerous autonomous capabilities. Under the voluntary covenant, developers agreed to freeze model training runs if internal evaluation scores cross predefined risk thresholds until external safety boards authorize continuation.
Philanthropic organizations announced substantial endowments to fund open-source evaluation benchmarks, ensuring that smaller developer communities and independent academics can inspect model behaviors without commercial bias.
"Safety is not the enemy of innovation; it is the prerequisite for public trust and technological longevity."— Washington Frontier Safety Summit Joint Communiqué
Standardizing Cross-Lab Red-Teaming
Participating frontier labs agreed to participate in mutual blind testing, allowing competing safety engineers to test each other's pre-release weights for vulnerabilities before public deployment, establishing an unprecedented level of peer review within the technology industry.
Inquiries and discussions must maintain diplomatic civility, analytical depth, and factual accuracy.
Sign in with your Google account to contribute to diplomatic discussions
No reader commentary yet
Be the first verified reader to submit your diplomatic dispatch or critique.